
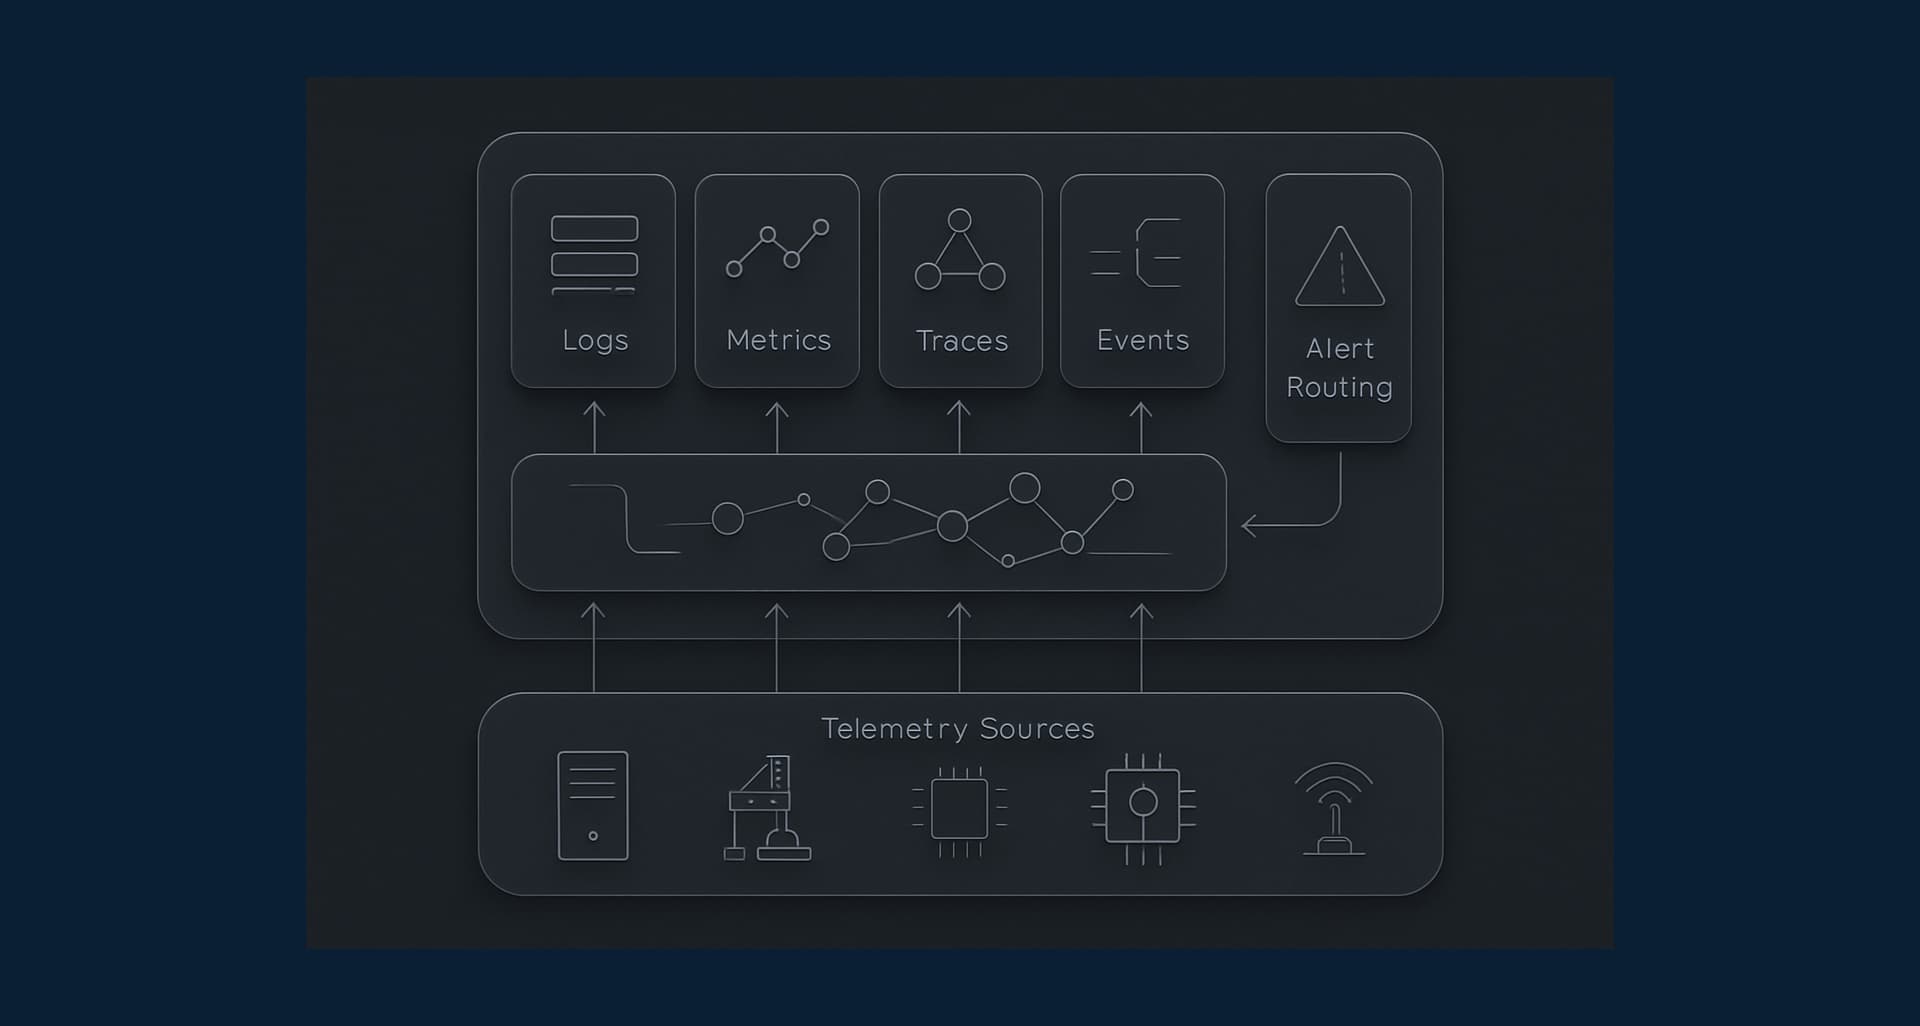
Observability gives teams a practical way to understand how distributed systems behave over time. Rather than relying on isolated alerts or scattered dashboards, it connects telemetry into a clearer operating picture. In edge environments, that context becomes especially important. Services may run across multiple locations, dependencies may shift quickly, and small failures can be difficult to trace without shared visibility. A useful observability approach brings together logs, metrics, traces, and events so teams can investigate issues with better accuracy. It also supports incident response, performance analysis, and ongoing reliability work. For MeteorEdge, observability is a design priority because operational clarity matters when systems are distributed. Better visibility helps teams diagnose problems earlier, review changes with more confidence, and maintain a stronger understanding of overall system health.